TRAIL (Trace Reasoning and Agentic Issue Localization) is a new benchmark dataset designed to evaluate how well SOTA large language models can debug and identify errors in complex AI agent workflows.
Evaluating agentic systems is significantly more challenging than debugging LLMs. While there are well-established approaches to debugging the input and output of LLMs, the errors from AI agent workflows can compound at every step and through interactions with external systems, making final debugging particularly challenging. Evaluating agentic systems requires tracing their chains of reasoning and actions, as well as all their interactions with environments. Existing evaluation approaches applied to LLMs and the manual debugging of agent management systems do not scale effectively.
To address this challenge, we created a novel taxonomy, grounded in LLM and agentic literature, that contains over 20 agentic errors, typically identified in traces, spanning reasoning, planning, and system execution errors.
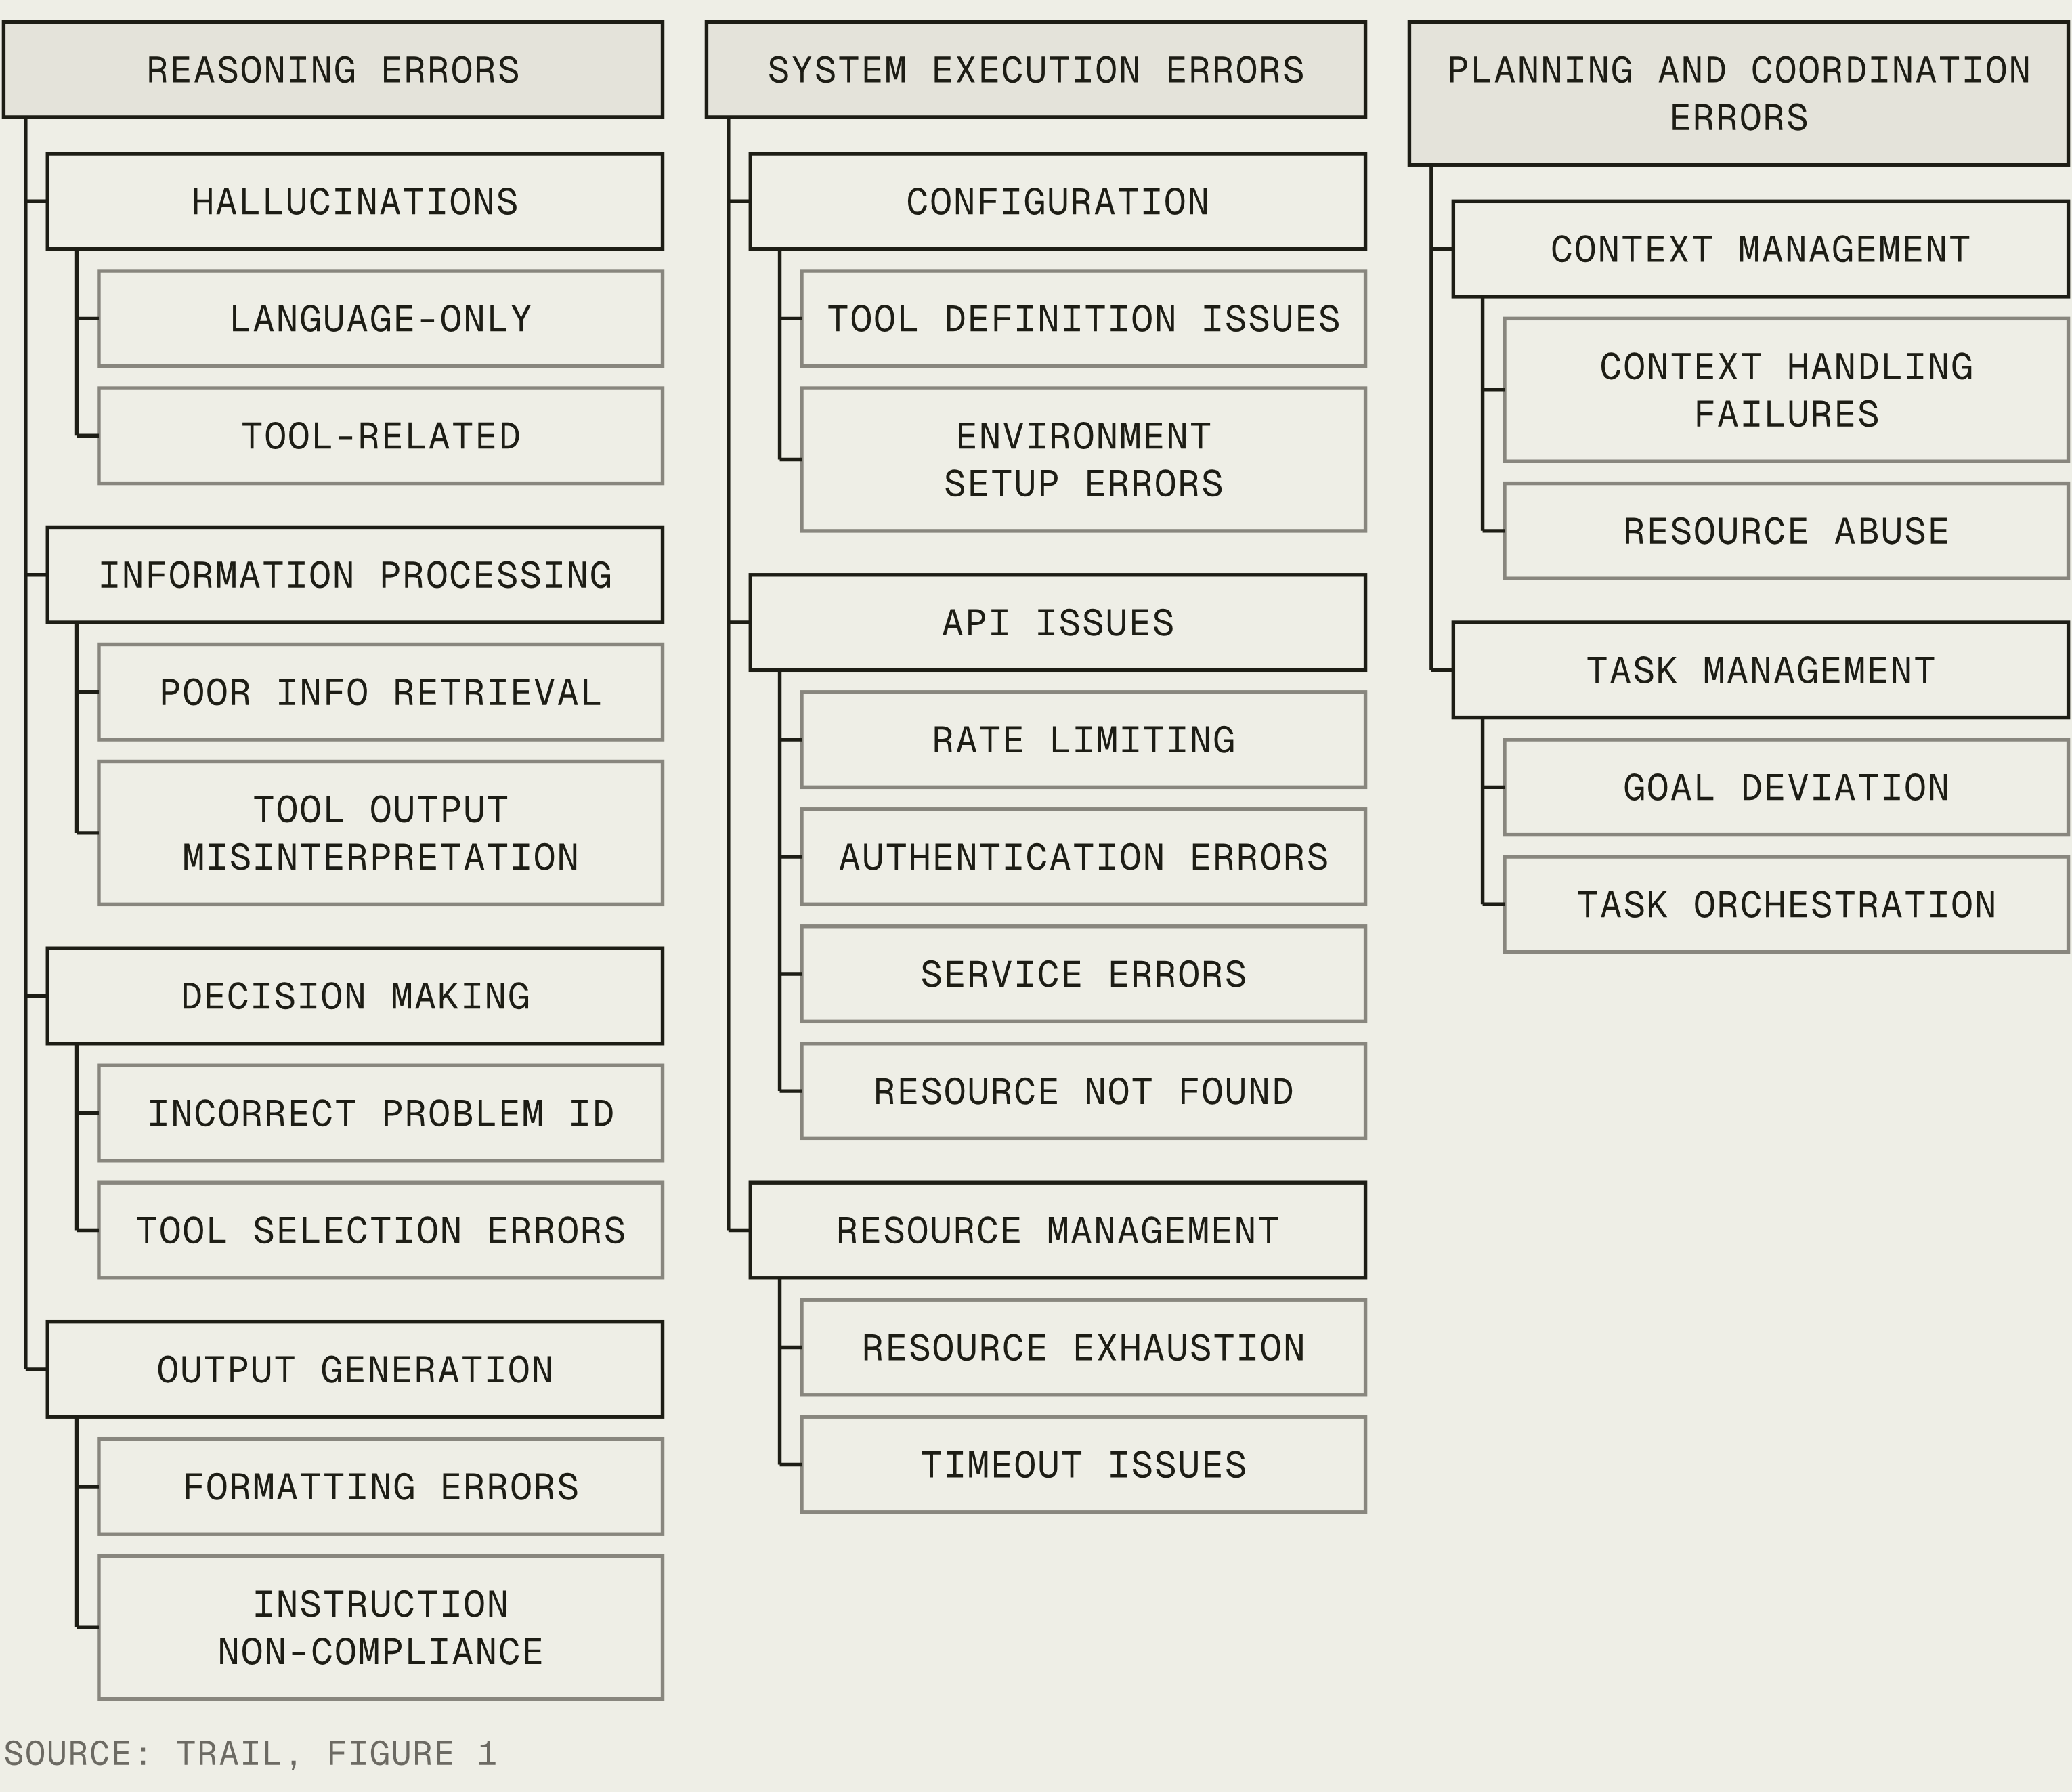
Following this taxonomy, we build on top of GAIA and SWE Bench to create TRAIL, a fully open-source benchmark with 148 human-annotated, long-context agentic traces containing 841 total errors (at an average of 5.68 errors and 110 annotation minutes per trace). The average number of input tokens is >200k, and the maximum is up to 6M tokens.
The benchmark is particularly challenging because it requires processing extremely long contexts that often exceed model context windows and demands significant output generation. For example, Claude takes in 200K tokens while Gemini takes in 1M for context. TRAIL includes traces from single-agent and multi-agent systems, making it valuable for improving LLMs' ability to evaluate complex agentic systems.
A preview of how SoTA models perform with reasoning set to ‘high’:
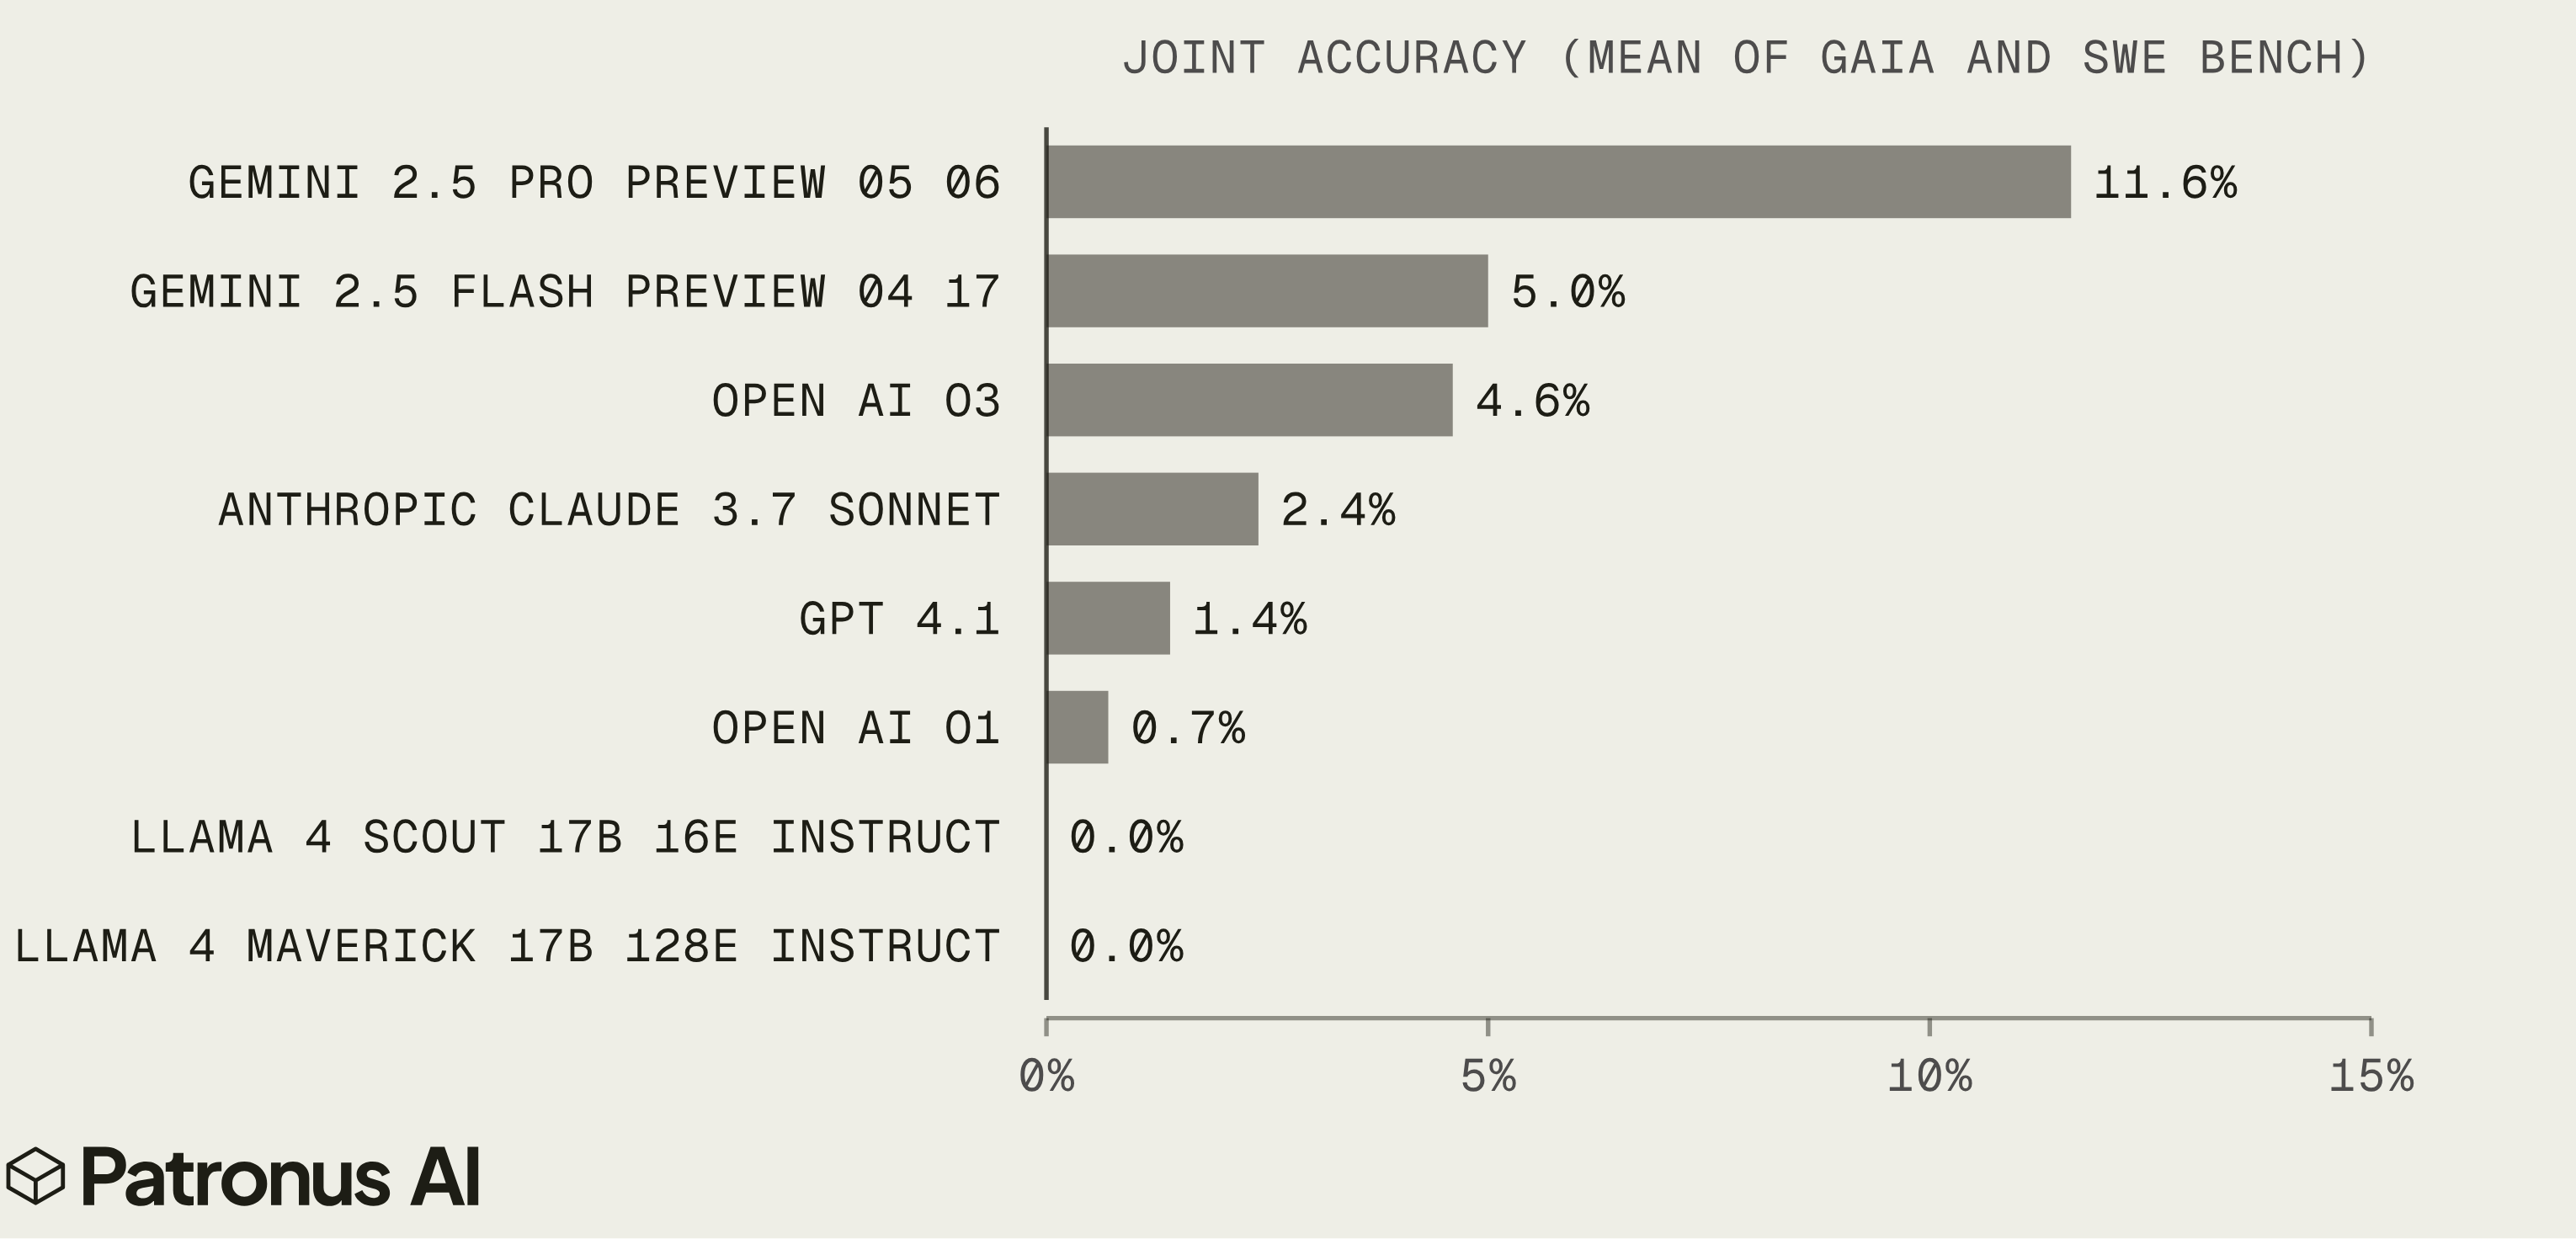
- Gemini-2.5-Pro-preview only achieves a joint accuracy of 11%
- Claude-3.7-Sonnet achieves 4.7%
- OpenAI’s o3 achieves 9.2%
Common error types for the SoTA models across the board include: task orchestration, tool-related, context handling failures, tool definition issues, and timeout issues. SOTA LLMs underperform in the planning & coordination steps, which have medium-to-high impact on the overall experience.
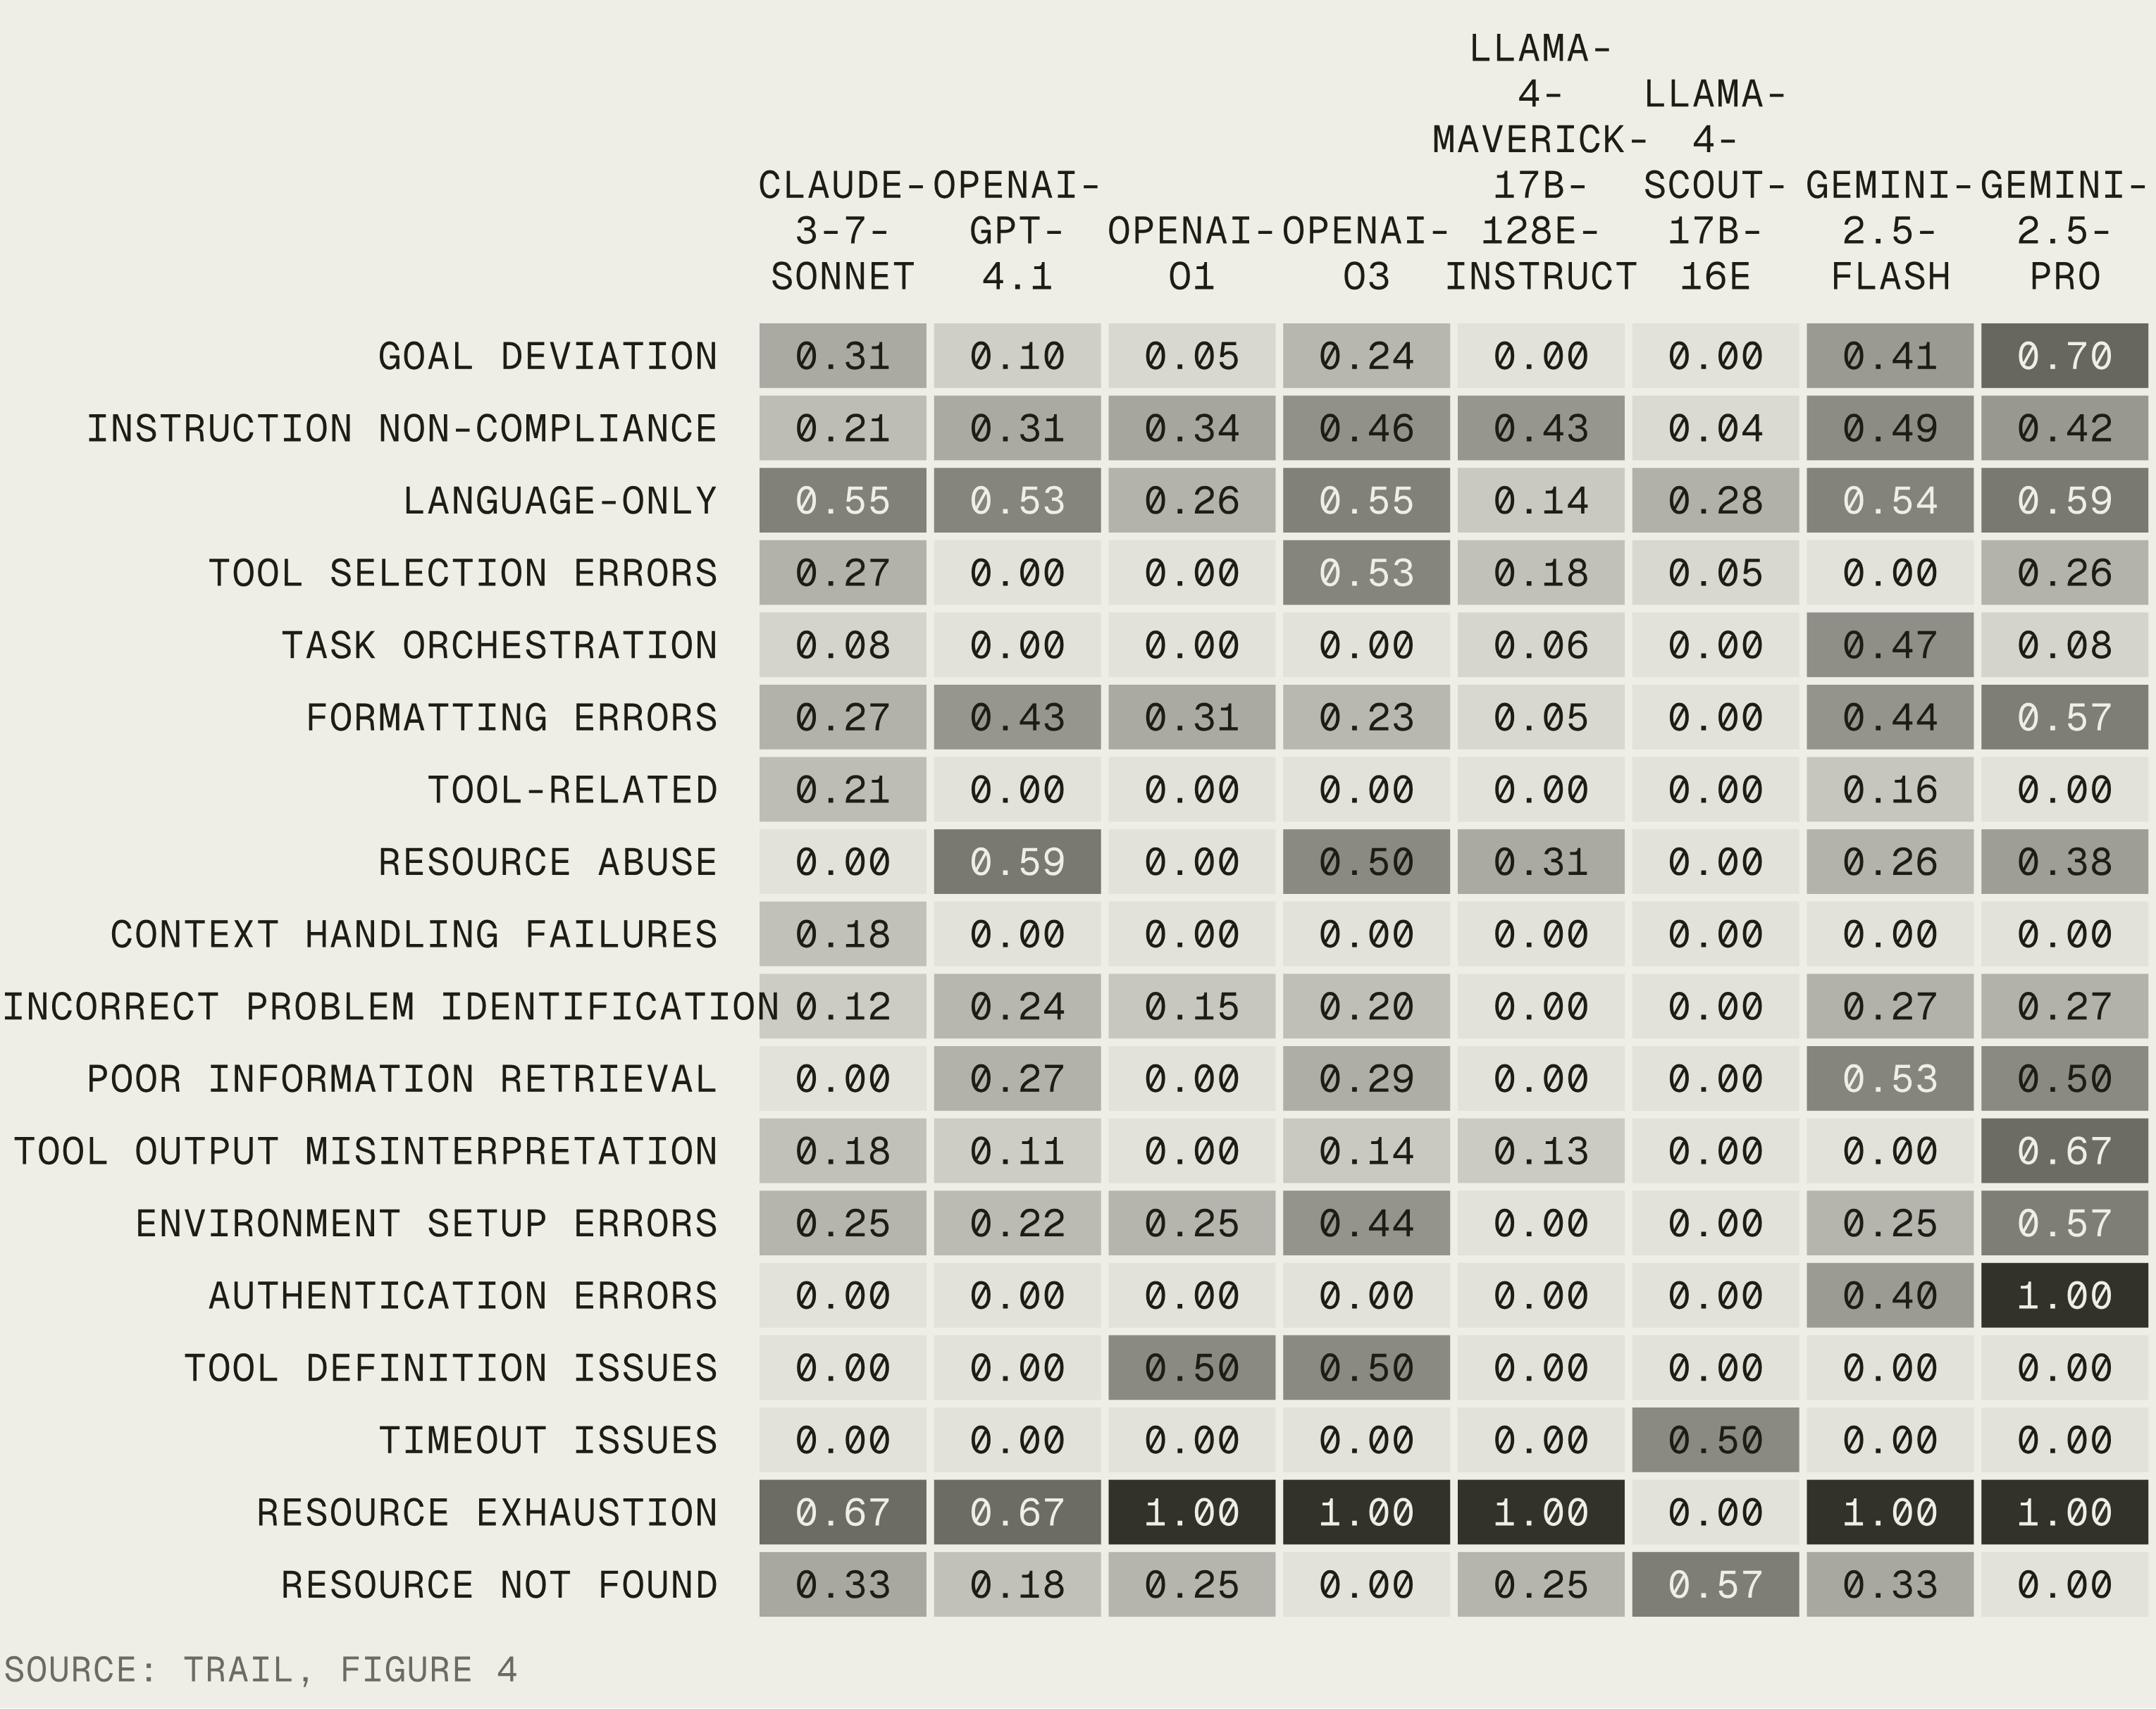
The team observed that increasing the number of reasoning output tokens improves performance. The SoTA models get <12% using “high” reasoning, showing that TRAIL is a non-trivially difficult benchmark.
Benchmark Release
arXiv Paper: Read the TRAIL paper
Hugging Face dataset: View the TRAIL dataset